RAGRAG for Technical Documentation
MSc thesis · RAG evaluation
Problem and goal
The project investigates how to give factory-floor and maintenance personnel fast, grounded answers about electronics defects documented in the visually complex IPC-A-610F standard.
My responsibility
I designed and built the experimental workflow used to compare document representations, retrieval configurations, generation choices, prompts, and evaluation results.
Design and experiments
The framework covers layout-aware parsing, structural and asset validation, synthetic dataset generation, dense, sparse and hybrid retrieval, reranking, generation models, prompt strategies, and evaluation with Ragas and Langfuse.
What the comparisons showed
Docling produced the most robust representation in the experiments. The best retrieval configuration used text-embedding-3-small, a three-chunk window, and no reranker. Domain-role framing removed refusal-style answers in the evaluated query set, while explicit instructions improved figure-reference retention.
Evaluation scope
The final configuration was checked against a separate 30% synthetic holdout set: questions reserved for the final evaluation. These findings describe the evaluated document and query set; they do not establish reliability for other documents or real factory use.
System pipelines
Parser selection
Pipeline 1: compare document parsers, build a structured graph, generate evaluation datasets, and select the most robust parser.
IPC-A-610F + candidate parsers↓Parse document and build graph↓Optimize graph and generate datasets↓Evaluate parsers in Langfuse↓Select best parser
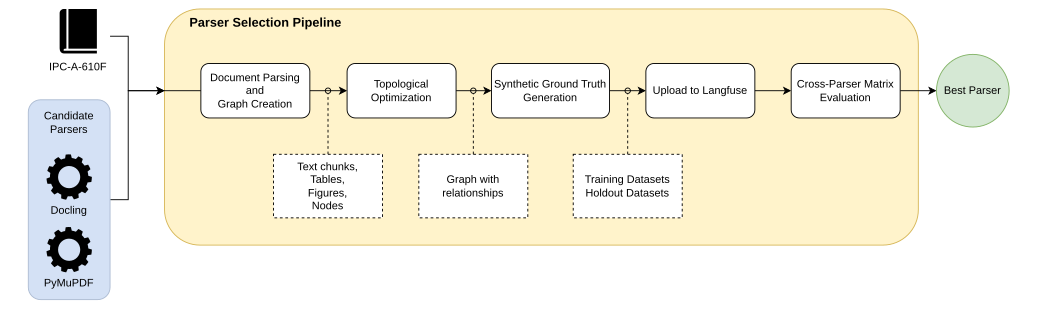 Open full parser-selection diagram
RAG optimization
Pipeline 2: optimize retrieval, generation, and prompts in sequence, then validate the final RAG configuration on held-out questions.
Vector database + ground truth + configurations↓Optimize retrieval↓Optimize LLM and prompt↓Validate on holdout dataset↓Select best RAG configuration
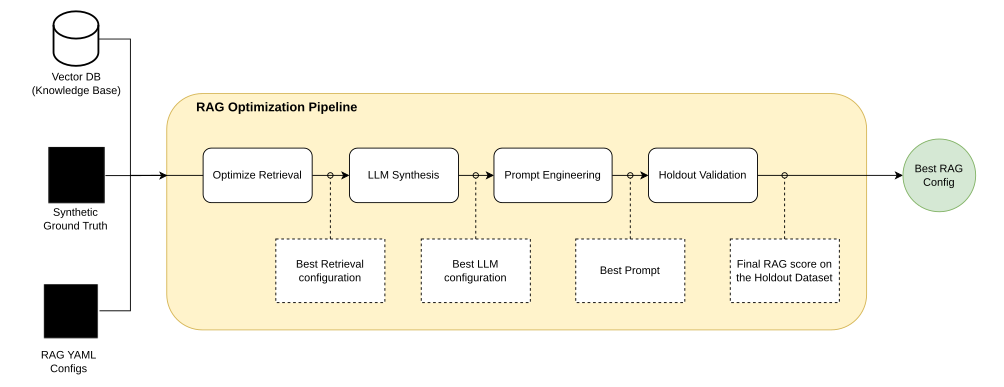 Open full RAG-optimization diagram